I recently attended CF Summit in Philadelphia in March 2019 and here is the talk track to that.
Metrics Driven Blue-green Deployments using Spinnaker’s Cloud Foundry Integration - Amith Nambiar & Pas Apicella, Pivotal
https://www.youtube.com/watch?v=9C8m7n_sG38
Friday, 3 May 2019


Thursday, 2 May 2019
Any App, Every Cloud, One Platform: Delivering on Pivotal’s Vision
Pivotal Cloud Foundry
(PCF) recently turned five-years-old. In celebration, Onsi Fakhouri reflects on how far the platform has come, and provides a look at our
plans for the months and years ahead.
The Pivotal Blog post exists here:
https://content.pivotal.io/blog/any-app-every-cloud-one-platform-delivering-on-pivotal-s-vision
The Pivotal Blog post exists here:
https://content.pivotal.io/blog/any-app-every-cloud-one-platform-delivering-on-pivotal-s-vision
Friday, 29 March 2019
Deploying an Application to Pivotal Cloud Foundry through Spinnaker and then invoking a resize operation
In this post we show a basic deployment to Cloud foundry in fact Pivotal Cloud foundry 2.4 using spinnaker 1.13.0.
Assumptions:
1. Configured a Cloud Foundry provider as shown below
spinnaker@myspinnaker-spinnaker-halyard-0:/workdir$ hal config provider cloudfoundry account add pez208 --user admin --password mypassword --api api.system.run.myenv.io --environment dev --appsManagerURI https://apps.system.run.myenv.io
+ Get current deployment
Success
+ Add the pez208 account
Success
Problems in default.provider.cloudfoundry:
- WARNING To be able to link server groups to CF Metrics a URI is
required: pez208
+ Successfully added account pez208 for provider cloudfoundry.
2. Enable cloud foundry provider
spinnaker@myspinnaker-spinnaker-halyard-0:/workdir$ hal config provider cloudfoundry enable
+ Get current deployment
Success
+ Edit the cloudfoundry provider
Success
+ Successfully enabled cloudfoundry
3. Run "hal deploy apply"
spinnaker@myspinnaker-spinnaker-halyard-0:/workdir$ hal deploy apply
+ Get current deployment
Success
+ Prep deployment
Success
+ Preparation complete... deploying Spinnaker
+ Get current deployment
Success
+ Apply deployment
Success
+ Deploy spin-clouddriver
Success
+ Deploy spin-front50
Success
+ Deploy spin-orca
Success
+ Deploy spin-deck
Success
+ Deploy spin-echo
Success
+ Deploy spin-gate
Success
+ Deploy spin-igor
Success
+ Deploy spin-rosco
Success
+ Run `hal deploy connect` to connect to Spinnaker.
IN this demo I can simply going to deploy my artifact sitting within my GitHub repo using a HTTP endpoiunt so for that will need to enable HTTP artifact support in Spinnaker as shown below
$ hal config features edit --artifacts true
$ hal config artifact http enable
$ hal config artifact http account add apples-http
$ hal deploy apply
Steps:
1. Lets create a new application called "pastest" as shown below. Be sure to select "CloudFoundry" provider.

2. Click "Create"
3. Click on "Create Server group"
4. Fill in the fields as shown below. In this example I am using the following

5. Click "Create"
6. Verify your application is going through the deploy phase as shown in the dialog

7. Oncer complete we can see our deployed application in Pivotal Cloud Foundry Applications Manager as shown below.

8. Now if we return to the Spinnaker UI we will see various views of what we just deployed as follows
Server Group Main Page

Load Balancer Page

Instance Page

9. Now let's actually scale our application to 2 instances rather than just a single instance. To do that lets click the "Resize Option" in the "Server Group Page" as shown below

10. In the dialog which appears set "Resize to" to "2"

11. Click "Submit"

12. Return to Pivotal Cloud Foundry Applications Manager and verify we now have 2 instances of our application as shown below

13. This will also be reflected on Spinnaker UI as well

More Information
Cloud Foundry - Cloud Provider
https://www.spinnaker.io/reference/providers/cf/
Assumptions:
1. Configured a Cloud Foundry provider as shown below
spinnaker@myspinnaker-spinnaker-halyard-0:/workdir$ hal config provider cloudfoundry account add pez208 --user admin --password mypassword --api api.system.run.myenv.io --environment dev --appsManagerURI https://apps.system.run.myenv.io
+ Get current deployment
Success
+ Add the pez208 account
Success
Problems in default.provider.cloudfoundry:
- WARNING To be able to link server groups to CF Metrics a URI is
required: pez208
+ Successfully added account pez208 for provider cloudfoundry.
2. Enable cloud foundry provider
spinnaker@myspinnaker-spinnaker-halyard-0:/workdir$ hal config provider cloudfoundry enable
+ Get current deployment
Success
+ Edit the cloudfoundry provider
Success
+ Successfully enabled cloudfoundry
3. Run "hal deploy apply"
spinnaker@myspinnaker-spinnaker-halyard-0:/workdir$ hal deploy apply
+ Get current deployment
Success
+ Prep deployment
Success
+ Preparation complete... deploying Spinnaker
+ Get current deployment
Success
+ Apply deployment
Success
+ Deploy spin-clouddriver
Success
+ Deploy spin-front50
Success
+ Deploy spin-orca
Success
+ Deploy spin-deck
Success
+ Deploy spin-echo
Success
+ Deploy spin-gate
Success
+ Deploy spin-igor
Success
+ Deploy spin-rosco
Success
+ Run `hal deploy connect` to connect to Spinnaker.
IN this demo I can simply going to deploy my artifact sitting within my GitHub repo using a HTTP endpoiunt so for that will need to enable HTTP artifact support in Spinnaker as shown below
$ hal config features edit --artifacts true
$ hal config artifact http enable
$ hal config artifact http account add apples-http
$ hal deploy apply
Steps:
1. Lets create a new application called "pastest" as shown below. Be sure to select "CloudFoundry" provider.

2. Click "Create"
3. Click on "Create Server group"
4. Fill in the fields as shown below. In this example I am using the following
- Account "pez208" which was the cloud foundry provider name we used above
- Region is basically the CF space we will deploy into
- HTTP artifact which I enabled called "apples-http".
- Fully qualified path to my JAR file I wish to deploy
- Form based manifest settings to define my application deployment settings

5. Click "Create"
6. Verify your application is going through the deploy phase as shown in the dialog

7. Oncer complete we can see our deployed application in Pivotal Cloud Foundry Applications Manager as shown below.

8. Now if we return to the Spinnaker UI we will see various views of what we just deployed as follows
Server Group Main Page

Load Balancer Page

Instance Page

9. Now let's actually scale our application to 2 instances rather than just a single instance. To do that lets click the "Resize Option" in the "Server Group Page" as shown below

10. In the dialog which appears set "Resize to" to "2"

11. Click "Submit"

12. Return to Pivotal Cloud Foundry Applications Manager and verify we now have 2 instances of our application as shown below

13. This will also be reflected on Spinnaker UI as well

More Information
Cloud Foundry - Cloud Provider
https://www.spinnaker.io/reference/providers/cf/
Thursday, 28 March 2019
Two nice Pivotal Container Service (PKS) CLI commands I use very often
Having always created multiple PKS clusters at times I forget the configuration of my K8S clusters and this command comes in very handy
First lets list those clusters we have created with PKS
papicella@papicella:~$ pks clusters
Name Plan Name UUID Status Action
lemons small 5c19c39e-88ae-4e06-a1cf-050b517f1b9c succeeded CREATE
banana small 7c3ab1b3-a25c-498e-8179-9a14336004ff succeeded CREATE
Now lets see how many master nodes and how many worker nodes actually exist in my cluster using "pks cluster {name} --json"
papicella@papicella:~$ pks cluster banana --json
{
"name": "banana",
"plan_name": "small",
"last_action": "CREATE",
"last_action_state": "succeeded",
"last_action_description": "Instance provisioning completed",
"uuid": "7c3ab1b3-a25c-498e-8179-9a14336004ff",
"kubernetes_master_ips": [
"10.0.0.1"
],
"parameters": {
"kubernetes_master_host": "banana.yyyy.hhh.pivotal.io",
"kubernetes_master_port": 8443,
"kubernetes_worker_instances": 3
}
}
One final PKS CLI command I use often when creating my clusters is the --wait option so I know when it's done creating the cluster rather then continually checking using "pks cluster {name}"
papicella@papicella:~$ pks create-cluster cluster1 -e cluster1.run.yyyy.hhh.pivotal.io -p small -n 4 --wait
More Information
https://docs.pivotal.io/runtimes/pks/1-3/cli/index.html
Wednesday, 6 March 2019

Thursday, 14 February 2019
Integrating Cloud Foundry with Spinnaker
I previously blogged about "Installing Spinnaker on Pivotal Container Service (PKS) with NSX-T running on vSphere" and then how to invoke UI using a "kubectl port-forward".
http://theblasfrompas.blogspot.com/2019/02/installing-spinnaker-on-pivotal.html
http://theblasfrompas.blogspot.com/2019/02/exposing-spinnaker-ui-endpoint-from.html
Steps
1. Exec into hal pod using a command as follows:
$ kubectl exec --namespace default -it myspinnaker-spinnaker-halyard-0 bash
Note: You can get the POD name as follows
papicella@papicella:~$ kubectl get pods | grep halyard
myspinnaker-spinnaker-halyard-0 1/1 Running 0 6d
2. Create a file settings-local.js in the directory ~/.hal/default/profiles/
window.spinnakerSettings.providers.cloudfoundry = {
defaults: {account: 'my-cloudfoundry-account'}
};
3. Create a file clouddriver-local.yml with contents as follows. You can add multiple accounts but in this example I am just adding one
cloudfoundry:
enabled: true
accounts:
- name: PWS
user: papicella-pas@pivotal.io
password: yyyyyyy
api: api.run.pivotal.io
4. If you are working with an existing installation of Spinnaker, apply your changes:
spinnaker@myspinnaker-spinnaker-halyard-0:~/.hal/default/profiles$ hal deploy apply
+ Get current deployment
Success
+ Prep deployment
Success
Problems in halconfig:
- WARNING There is a newer version of Halyard available (1.15.0),
please update when possible
? Run 'sudo apt-get update && sudo apt-get install
spinnaker-halyard -y' to upgrade
+ Preparation complete... deploying Spinnaker
+ Get current deployment
Success
+ Apply deployment
Success
+ Run `hal deploy connect` to connect to Spinnaker.
5. Once this is done in the UI you will see any applications in your Organisations appear in this example it's a single application called "Spring" as shown below

6. In the example below when "Creating an Application" we can select the ORGS/Spaces we wish to use as shown below

More Information
Cloud Foundry Integration
https://www.spinnaker.io/setup/install/providers/cf/
Cloud Foundry Resource Mapping
https://www.spinnaker.io/reference/providers/cf/
Thursday, 7 February 2019
Spring Cloud GCP and authentication from your Spring Boot Application
When using Spring Cloud GCP you will need to authenticate at some point in order to use the GCP services. In this example below using a GCP Cloud SQL instance you really only need to do 3 things to access it externally from your Spring Boot application as follows.
1. Enable the Google Cloud SQL API which is detailed here
https://cloud.google.com/sql/docs/mysql/admin-api/
2. Ensure that your GCP SDK can login to your Google Cloud SQL. This command will take you to a web page asking which google account you want to use
$ gcloud auth application-default login
3. Finally some application properties in your Spring Boot application detailing the Google Cloud SQL instance name and database name as shown below.
spring.cloud.gcp.sql.instance-connection-name=fe-papicella:australia-southeast1:apples-db
spring.cloud.gcp.sql.database-name=employees
Now when you do that and your application starts up you will see a log message as follows below clearly warning you this this method of authentication can have implications at some point.
2019-02-07 09:10:26.700 WARN 2477 --- [ main] c.g.a.oauth2.DefaultCredentialsProvider : Your application has authenticated using end user credentials from Google Cloud SDK. We recommend that most server applications use service accounts instead. If your application continues to use end user credentials from Cloud SDK, you might receive a "quota exceeded" or "API not enabled" error. For more information about service accounts, see https://cloud.google.com/docs/authentication/.
Clearly that's something we have to resolve. To do that we simply can add another Spring Boot application property pointing to a service account JSON file for us to authenticate against to remove the warning.
spring.cloud.gcp.credentials.location=file:/Users/papicella/piv-projects/GCP/fe-papicella-8077fe1126b2.json
Note: You can also use an ENV variable as follows
export GOOGLE_APPLICATION_CREDENTIALS="[PATH]"
You can get a JSON key generated from the GCP console "IAM and Admin -> Service Accounts" page

For more information on authentication visit this link https://cloud.google.com/docs/authentication/getting-started
Tuesday, 22 January 2019
Testing out the new PFS (Pivotal Function Service) alpha release on minikube
I quickly installed PFS on minikube as per the instructions below so I could write my own function service. Below shows that function service and how I invoked using the PFS CLI and Postman
1. Install PFS using this url for minikube. Refer to these instructions to install PFS on minikube
https://docs.pivotal.io/pfs/install-on-minikube.html
2. Once installed verify PFS has been installed using some commands as follows
$ watch -n 1 kubectl get pod --all-namespaces
Output:

Various namespaces are created as shown below:
$ kubectl get namespaces
NAME STATUS AGE
default Active 19h
istio-system Active 18h
knative-build Active 18h
knative-eventing Active 18h
knative-serving Active 18h
kube-public Active 19h
kube-system Active 19h
Ensure PFS is installed as shown below:
$ pfs version
Version
pfs cli: 0.1.0 (e5de84d12d10a060aeb595310decbe7409467c99)
3. Now we are going to deploy this employee function which exists on GitHub as follows
https://github.com/papicella/emp-function-service

The Function code is as follows:
https://docs.pivotal.io/pfs/using-java-functions.html
5. Let's create a function called "emp-function" as shown below
$ pfs function create emp-function --git-repo https://github.com/papicella/emp-function-service --image $REGISTRY/$REGISTRY_USER/emp-function -w -v
Output: (Just showing the last few lines here)
papicella@papicella:~/pivotal/software/minikube$ pfs function create emp-function --git-repo https://github.com/papicella/emp-function-service --image $REGISTRY/$REGISTRY_USER/emp-function -w -v
Waiting for LatestCreatedRevisionName
Waiting on function creation: checkService failed to obtain service status for observedGeneration 1
LatestCreatedRevisionName available: emp-function-00001
...
default/emp-function-00001-gpn7p[build-step-build]: [INFO] BUILD SUCCESS
default/emp-function-00001-gpn7p[build-step-build]: [INFO] ------------------------------------------------------------------------
default/emp-function-00001-gpn7p[build-step-build]: [INFO] Total time: 12.407 s
default/emp-function-00001-gpn7p[build-step-build]: [INFO] Finished at: 2019-01-22T00:12:39Z
default/emp-function-00001-gpn7p[build-step-build]: [INFO] ------------------------------------------------------------------------
default/emp-function-00001-gpn7p[build-step-build]: Removing source code
default/emp-function-00001-gpn7p[build-step-build]:
default/emp-function-00001-gpn7p[build-step-build]: -----> riff Buildpack 0.1.0
default/emp-function-00001-gpn7p[build-step-build]: -----> riff Java Invoker 0.1.3: Contributing to launch
default/emp-function-00001-gpn7p[build-step-build]: Reusing cached download from buildpack
default/emp-function-00001-gpn7p[build-step-build]: Copying to /workspace/io.projectriff.riff/riff-invoker-java/java-function-invoker-0.1.3-exec.jar
default/emp-function-00001-gpn7p[build-step-build]: -----> Process types:
default/emp-function-00001-gpn7p[build-step-build]: web: java -jar /workspace/io.projectriff.riff/riff-invoker-java/java-function-invoker-0.1.3-exec.jar $JAVA_OPTS --function.uri='file:///workspace/app'
default/emp-function-00001-gpn7p[build-step-build]: function: java -jar /workspace/io.projectriff.riff/riff-invoker-java/java-function-invoker-0.1.3-exec.jar $JAVA_OPTS --function.uri='file:///workspace/app'
default/emp-function-00001-gpn7p[build-step-build]:
...
default/emp-function-00001-deployment-66fbd6bf4-bbqpq[user-container]: Hibernate: insert into employee (id, name) values (null, ?)
default/emp-function-00001-deployment-66fbd6bf4-bbqpq[user-container]: 2019-01-22 00:13:53.617 INFO 1 --- [ Thread-4] c.e.empfunctionservice.LoadDatabase : Preloading Employee(id=1, name=pas)
default/emp-function-00001-deployment-66fbd6bf4-bbqpq[user-container]: Hibernate: insert into employee (id, name) values (null, ?)
default/emp-function-00001-deployment-66fbd6bf4-bbqpq[user-container]: 2019-01-22 00:13:53.623 INFO 1 --- [ Thread-4] c.e.empfunctionservice.LoadDatabase : Preloading Employee(id=2, name=lucia)
default/emp-function-00001-deployment-66fbd6bf4-bbqpq[user-container]: Hibernate: insert into employee (id, name) values (null, ?)
default/emp-function-00001-deployment-66fbd6bf4-bbqpq[user-container]: 2019-01-22 00:13:53.628 INFO 1 --- [ Thread-4] c.e.empfunctionservice.LoadDatabase : Preloading Employee(id=3, name=lucas)
default/emp-function-00001-deployment-66fbd6bf4-bbqpq[user-container]: Hibernate: insert into employee (id, name) values (null, ?)
default/emp-function-00001-deployment-66fbd6bf4-bbqpq[user-container]: 2019-01-22 00:13:53.632 INFO 1 --- [ Thread-4] c.e.empfunctionservice.LoadDatabase : Preloading Employee(id=4, name=siena)
default/emp-function-00001-deployment-66fbd6bf4-bbqpq[user-container]: 2019-01-22 00:13:53.704 INFO 1 --- [ Thread-2] o.s.c.f.d.FunctionCreatorConfiguration : Located bean: findEmployee of type class com.example.empfunctionservice.EmpFunctionServiceApplication$$Lambda$791/373359604
pfs function create completed successfully
6. Let's invoke our function as shown below by returning each Employee record using it's ID.
$ pfs service invoke emp-function --text -- -w '\n' -d '1'
curl http://192.168.64.3:32380/ -H 'Host: emp-function.default.example.com' -H 'Content-Type: text/plain' -w '\n' -d 1
Employee(id=1, name=pas)
$ pfs service invoke emp-function --text -- -w '\n' -d '2'
curl http://192.168.64.3:32380/ -H 'Host: emp-function.default.example.com' -H 'Content-Type: text/plain' -w '\n' -d 2
Employee(id=2, name=lucia)
The "pfs service invoke" will show you what an external command will look like to invoke the function service. The IP address here is just the same IP address returned by "minikube ip" as shown below.
$ minikube ip
192.168.64.3
7. Let's view our services using "pfs" CLI
$ pfs service list
NAME STATUS
emp-function Running
hello Running
pfs service list completed successfully
8. Invoking from Postman, ensuring we issue a POST request and pass the correct headers as shown below


More Information
https://docs.pivotal.io/pfs/index.html
1. Install PFS using this url for minikube. Refer to these instructions to install PFS on minikube
https://docs.pivotal.io/pfs/install-on-minikube.html
2. Once installed verify PFS has been installed using some commands as follows
$ watch -n 1 kubectl get pod --all-namespaces
Output:

Various namespaces are created as shown below:
$ kubectl get namespaces
NAME STATUS AGE
default Active 19h
istio-system Active 18h
knative-build Active 18h
knative-eventing Active 18h
knative-serving Active 18h
kube-public Active 19h
kube-system Active 19h
Ensure PFS is installed as shown below:
$ pfs version
Version
pfs cli: 0.1.0 (e5de84d12d10a060aeb595310decbe7409467c99)
3. Now we are going to deploy this employee function which exists on GitHub as follows
https://github.com/papicella/emp-function-service
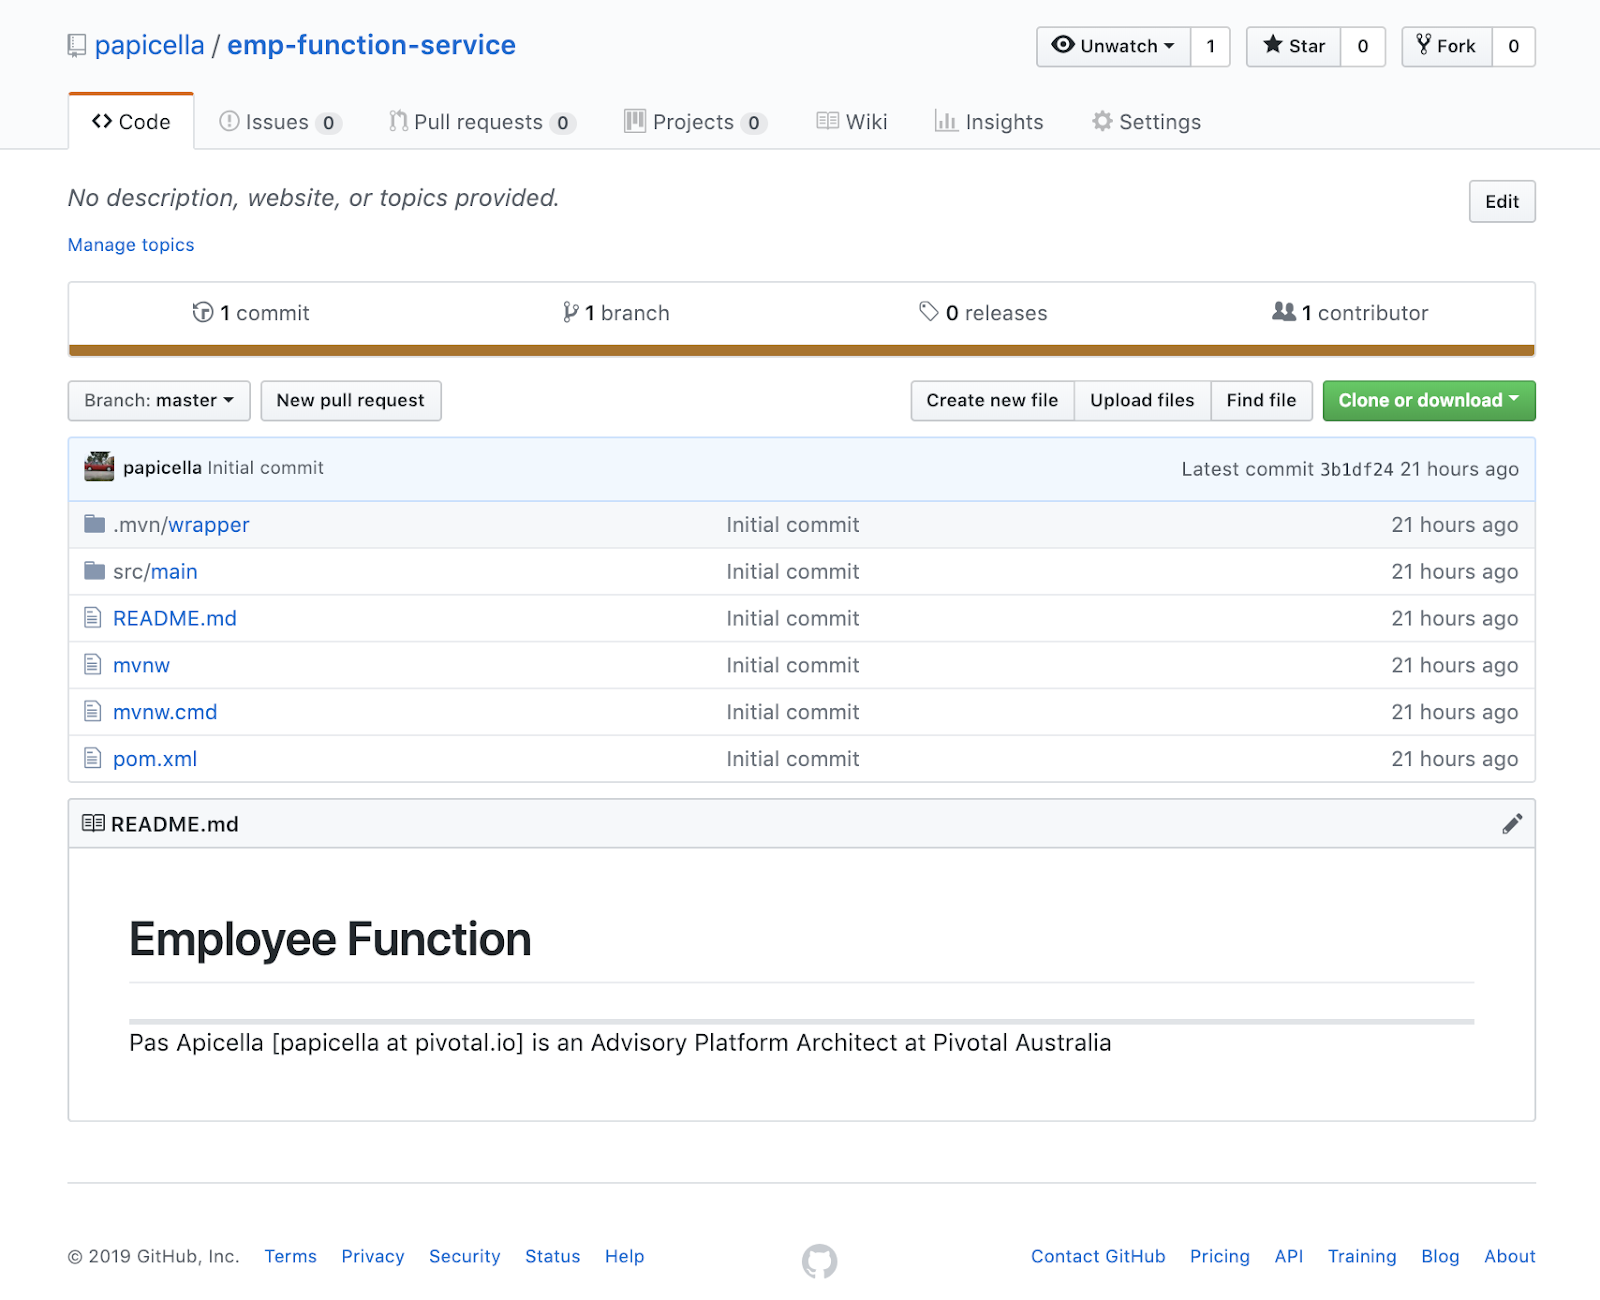
The Function code is as follows:
package com.example.empfunctionservice;

import lombok.extern.slf4j.Slf4j;
import org.springframework.boot.SpringApplication;
import org.springframework.boot.autoconfigure.SpringBootApplication;
import org.springframework.context.annotation.Bean;

import java.util.function.Function;

@Slf4j
@SpringBootApplication
public class EmpFunctionServiceApplication {

    private static EmployeeService employeeService;

    public EmpFunctionServiceApplication(EmployeeService employeeService) {
        this.employeeService = employeeService;
    }

    @Bean
    public Function<String, String> findEmployee() {
        return id -> {
            String response = employeeService.getEmployee(id);

            return response;
        };
    }

    public static void main(String[] args) {
        SpringApplication.run(EmpFunctionServiceApplication.class, args);
    }

}
4. We are going to deploy a Spring Boot Function as per the REPO above. More information on Java Functions for PFS can be found here
https://docs.pivotal.io/pfs/using-java-functions.html
5. Let's create a function called "emp-function" as shown below
$ pfs function create emp-function --git-repo https://github.com/papicella/emp-function-service --image $REGISTRY/$REGISTRY_USER/emp-function -w -v
Output: (Just showing the last few lines here)
papicella@papicella:~/pivotal/software/minikube$ pfs function create emp-function --git-repo https://github.com/papicella/emp-function-service --image $REGISTRY/$REGISTRY_USER/emp-function -w -v
Waiting for LatestCreatedRevisionName
Waiting on function creation: checkService failed to obtain service status for observedGeneration 1
LatestCreatedRevisionName available: emp-function-00001
...
default/emp-function-00001-gpn7p[build-step-build]: [INFO] BUILD SUCCESS
default/emp-function-00001-gpn7p[build-step-build]: [INFO] ------------------------------------------------------------------------
default/emp-function-00001-gpn7p[build-step-build]: [INFO] Total time: 12.407 s
default/emp-function-00001-gpn7p[build-step-build]: [INFO] Finished at: 2019-01-22T00:12:39Z
default/emp-function-00001-gpn7p[build-step-build]: [INFO] ------------------------------------------------------------------------
default/emp-function-00001-gpn7p[build-step-build]: Removing source code
default/emp-function-00001-gpn7p[build-step-build]:
default/emp-function-00001-gpn7p[build-step-build]: -----> riff Buildpack 0.1.0
default/emp-function-00001-gpn7p[build-step-build]: -----> riff Java Invoker 0.1.3: Contributing to launch
default/emp-function-00001-gpn7p[build-step-build]: Reusing cached download from buildpack
default/emp-function-00001-gpn7p[build-step-build]: Copying to /workspace/io.projectriff.riff/riff-invoker-java/java-function-invoker-0.1.3-exec.jar
default/emp-function-00001-gpn7p[build-step-build]: -----> Process types:
default/emp-function-00001-gpn7p[build-step-build]: web: java -jar /workspace/io.projectriff.riff/riff-invoker-java/java-function-invoker-0.1.3-exec.jar $JAVA_OPTS --function.uri='file:///workspace/app'
default/emp-function-00001-gpn7p[build-step-build]: function: java -jar /workspace/io.projectriff.riff/riff-invoker-java/java-function-invoker-0.1.3-exec.jar $JAVA_OPTS --function.uri='file:///workspace/app'
default/emp-function-00001-gpn7p[build-step-build]:
...
default/emp-function-00001-deployment-66fbd6bf4-bbqpq[user-container]: Hibernate: insert into employee (id, name) values (null, ?)
default/emp-function-00001-deployment-66fbd6bf4-bbqpq[user-container]: 2019-01-22 00:13:53.617 INFO 1 --- [ Thread-4] c.e.empfunctionservice.LoadDatabase : Preloading Employee(id=1, name=pas)
default/emp-function-00001-deployment-66fbd6bf4-bbqpq[user-container]: Hibernate: insert into employee (id, name) values (null, ?)
default/emp-function-00001-deployment-66fbd6bf4-bbqpq[user-container]: 2019-01-22 00:13:53.623 INFO 1 --- [ Thread-4] c.e.empfunctionservice.LoadDatabase : Preloading Employee(id=2, name=lucia)
default/emp-function-00001-deployment-66fbd6bf4-bbqpq[user-container]: Hibernate: insert into employee (id, name) values (null, ?)
default/emp-function-00001-deployment-66fbd6bf4-bbqpq[user-container]: 2019-01-22 00:13:53.628 INFO 1 --- [ Thread-4] c.e.empfunctionservice.LoadDatabase : Preloading Employee(id=3, name=lucas)
default/emp-function-00001-deployment-66fbd6bf4-bbqpq[user-container]: Hibernate: insert into employee (id, name) values (null, ?)
default/emp-function-00001-deployment-66fbd6bf4-bbqpq[user-container]: 2019-01-22 00:13:53.632 INFO 1 --- [ Thread-4] c.e.empfunctionservice.LoadDatabase : Preloading Employee(id=4, name=siena)
default/emp-function-00001-deployment-66fbd6bf4-bbqpq[user-container]: 2019-01-22 00:13:53.704 INFO 1 --- [ Thread-2] o.s.c.f.d.FunctionCreatorConfiguration : Located bean: findEmployee of type class com.example.empfunctionservice.EmpFunctionServiceApplication$$Lambda$791/373359604
pfs function create completed successfully
6. Let's invoke our function as shown below by returning each Employee record using it's ID.
$ pfs service invoke emp-function --text -- -w '\n' -d '1'
curl http://192.168.64.3:32380/ -H 'Host: emp-function.default.example.com' -H 'Content-Type: text/plain' -w '\n' -d 1
Employee(id=1, name=pas)
$ pfs service invoke emp-function --text -- -w '\n' -d '2'
curl http://192.168.64.3:32380/ -H 'Host: emp-function.default.example.com' -H 'Content-Type: text/plain' -w '\n' -d 2
Employee(id=2, name=lucia)
The "pfs service invoke" will show you what an external command will look like to invoke the function service. The IP address here is just the same IP address returned by "minikube ip" as shown below.
$ minikube ip
192.168.64.3
7. Let's view our services using "pfs" CLI
$ pfs service list
NAME STATUS
emp-function Running
hello Running
pfs service list completed successfully
8. Invoking from Postman, ensuring we issue a POST request and pass the correct headers as shown below


More Information
https://docs.pivotal.io/pfs/index.html
Friday, 4 January 2019
Creating a local kubectl config file for the proxy to your Kubernetes API server
On my Mac accessing the CONFIG file of kubectl exist in a painful location as follows
$HOME/.kube/config
When using the command "kubectl proxy" and invoking the UI requires you to browse to the CONFIG file which finder doesn't expose easily. One way around this is as follows
1. Save a copy of that config file in your current directory as follows
papicella@papicella:~/temp$ cat ~/.kube/config > kubeconfig
2. Invoke "kubectl proxy" to start a UI server to your K8's cluster
papicella@papicella:~/temp$ kubectl proxy
Starting to serve on 127.0.0.1:8001
3. Navigate to the UI using an URL as follows
http://localhost:8001/api/v1/namespaces/kube-system/services/https:kubernetes-dashboard:/proxy/#!/overview

4. At this point we can browse to the easily accessible TEMP directory to the file "kubeconfig" we created at step #1 and then click "Sing In" button

Thursday, 13 December 2018
PCF Heathwatch 1.4 just got a new UI
PCF Healthwatch is a service for monitoring and alerting on the current health, performance, and capacity of PCF to help operators understand the operational state of their PCF deployment
Finally got around to installing the new PCF Healthwatch 1.4 and the first thing which struck me was the UI main dashboard page. It's clear what I need to look at in seconds and the alerts on the right hand side also useful
Some screen shots below


papicella@papicella:~/pivotal/PCF/APJ/PEZ-HaaS/haas-99$ http http://healthwatch.run.haas-99.pez.pivotal.io/info
HTTP/1.1 200 OK
Content-Length: 45
Content-Type: application/json;charset=utf-8
Date: Thu, 13 Dec 2018 10:26:07 GMT
X-Vcap-Request-Id: ac309698-74a6-4e94-429a-bb5673c1c8f7
{
"message": "PCF Healthwatch available"
}
More Information
Pivotal Cloud Foundry Healthwatch
https://docs.pivotal.io/pcf-healthwatch/1-4/index.html
Monday, 10 December 2018
Disabling Spring Security if you don't require it
When using Spring Cloud Services Starter Config Client dependency for example Spring Security will also be included (Config servers will be protected by OAuth2). As a result this will also enable basic authentication to all our service endpoints on your application which may not be the desired result here if your just building a demo for example
Add the following to conditionally disable security in your Spring Boot main class
Add the following to conditionally disable security in your Spring Boot main class
package com.example.employeeservice;

import org.springframework.boot.SpringApplication;
import org.springframework.boot.autoconfigure.SpringBootApplication;

import org.springframework.cloud.client.discovery.EnableDiscoveryClient;
import org.springframework.context.annotation.Configuration;
import org.springframework.security.config.annotation.web.builders.WebSecurity;
import org.springframework.security.config.annotation.web.configuration.WebSecurityConfigurerAdapter;

@SpringBootApplication
@EnableDiscoveryClient
public class EmployeeServiceApplication {

    public static void main(String[] args) {
        SpringApplication.run(EmployeeServiceApplication.class, args);
    }

    @Configuration
    static class ApplicationSecurity extends WebSecurityConfigurerAdapter {

        @Override
        public void configure(WebSecurity web) throws Exception {
            web
                    .ignoring()
                    .antMatchers("/**");
        }
    }
}
Saturday, 8 December 2018
The First Open, Multi-cloud Serverless Platform for the Enterprise Is Here
That’s Pivotal Function Service, and it’s available as an alpha release today. Read more about it here
https://content.pivotal.io/blog/the-first-open-multi-cloud-serverless-platform-for-the-enterprise-is-here-try-out-pivotal-function-service-today
Docs as follows
https://docs.pivotal.io/pfs/index.html
https://content.pivotal.io/blog/the-first-open-multi-cloud-serverless-platform-for-the-enterprise-is-here-try-out-pivotal-function-service-today
Docs as follows
https://docs.pivotal.io/pfs/index.html
Monday, 8 October 2018
Spring Cloud GCP using Spring Data JPA with MySQL 2nd Gen 5.7
Spring Cloud GCP adds integrations with
Spring JDBC
so you can run your MySQL or PostgreSQL databases in Google Cloud SQL using Spring JDBC, or other
libraries that depend on it like Spring Data JPA. Here is an example of how using Spring Data JPA with "Spring Cloud GCP"
1. First we need a MySQL 2nd Gen 5.7 database to exist in our GCP account which I have previously created as shown below


2. Create a new project using Spring Initializer or how ever you like to create it BUT ensure you have the following dependencies in place. Here is an example of what my pom.xml looks like. In short add the following maven dependencies as per the image below

pom.xml
3. Let's start by creating a basic Employee entity as shown below
Employee.java
4. Let's now add a Rest JpaRepository for our Entity
EmployeeRepository.java
EmployeeRest.java
6. Let's create an ApplicationRunner to show our list of Employees as the applications starts up
EmployeeRunner.java
data.sql
insert into employee (name) values ('pas');
insert into employee (name) values ('lucia');
insert into employee (name) values ('lucas');
insert into employee (name) values ('siena');
8. Finally our "application.yml" file will need to be able to be able to connect to our MySQL instance running in GCP as well as set some properties for JPA as shown below
spring:
jpa:
hibernate:
ddl-auto: create-drop
use-new-id-generator-mappings: false
properties:
hibernate:
dialect: org.hibernate.dialect.MariaDB53Dialect
cloud:
gcp:
sql:
instance-connection-name: fe-papicella:australia-southeast1:apples-mysql-1
database-name: employees
datasource:
initialization-mode: always
hikari:
maximum-pool-size: 1
A couple of things in here which are important.
- Set the Hibernate property "dialect: org.hibernate.dialect.MariaDB53Dialect" otherwise without this when hibernate creates tables for your entities you will run into this error as Cloud SQL database tables are created using the InnoDB storage engine.
ERROR 3161 (HY000): Storage engine MyISAM is disabled (Table creation is disallowed).
- For a demo I don't need multiple DB connections so I set the datasource "maximum-pool-size" to 1
- Notice how I set the "instance-connection-name" and "database-name" which is vital for Spring Cloud SQL to establish database connections
8. Now we need to make sure we have a database called "employees" as per our "application.yml" setting.

9. Now let's run our Spring Boot Application and verify this working showing some output from the logs
- Connection being established
2018-10-08 10:54:37.333 INFO 89922 --- [ main] c.google.cloud.sql.mysql.SocketFactory : Connecting to Cloud SQL instance [fe-papicella:australia-southeast1:apples-mysql-1] via ssl socket.
2018-10-08 10:54:37.335 INFO 89922 --- [ main] c.g.cloud.sql.core.SslSocketFactory : First Cloud SQL connection, generating RSA key pair.
2018-10-08 10:54:38.685 INFO 89922 --- [ main] c.g.cloud.sql.core.SslSocketFactory : Obtaining ephemeral certificate for Cloud SQL instance [fe-papicella:australia-southeast1:apples-mysql-1].
2018-10-08 10:54:40.132 INFO 89922 --- [ main] c.g.cloud.sql.core.SslSocketFactory : Connecting to Cloud SQL instance [fe-papicella:australia-southeast1:apples-mysql-1] on IP [35.197.180.223].
2018-10-08 10:54:40.748 INFO 89922 --- [ main] com.zaxxer.hikari.HikariDataSource : HikariPool-1 - Start completed.
- Showing the 4 Employee records
Employee(id=1, name=pas)
Employee(id=2, name=lucia)
Employee(id=3, name=lucas)
Employee(id=4, name=siena)
10. Finally let's make RESTful call as we defined above using HTTPie as follows
pasapicella@pas-macbook:~$ http :8080/emps-rest
HTTP/1.1 200
Content-Type: application/json;charset=UTF-8
Date: Mon, 08 Oct 2018 00:01:42 GMT
Transfer-Encoding: chunked
[
{
"id": 1,
"name": "pas"
},
{
"id": 2,
"name": "lucia"
},
{
"id": 3,
"name": "lucas"
},
{
"id": 4,
"name": "siena"
}
]
More Information
Spring Cloud GCP
https://cloud.spring.io/spring-cloud-gcp/
Spring Cloud GCP SQL demo (This one is using Spring JDBC)
https://github.com/spring-cloud/spring-cloud-gcp/tree/master/spring-cloud-gcp-samples/spring-cloud-gcp-sql-sample
1. First we need a MySQL 2nd Gen 5.7 database to exist in our GCP account which I have previously created as shown below


2. Create a new project using Spring Initializer or how ever you like to create it BUT ensure you have the following dependencies in place. Here is an example of what my pom.xml looks like. In short add the following maven dependencies as per the image below

pom.xml
<parent>
    <groupId>org.springframework.boot</groupId>
    <artifactId>spring-boot-starter-parent</artifactId>
    <version>2.0.5.RELEASE</version>
    <relativePath/> <!-- lookup parent from repository -->
</parent>

<properties>
    <project.build.sourceEncoding>UTF-8</project.build.sourceEncoding>
    <project.reporting.outputEncoding>UTF-8</project.reporting.outputEncoding>
    <java.version>1.8</java.version>
    <spring-cloud-gcp.version>1.0.0.RELEASE</spring-cloud-gcp.version>
    <spring-cloud.version>Finchley.SR1</spring-cloud.version>
</properties>

<dependencies>
    <dependency>
        <groupId>org.springframework.boot</groupId>
        <artifactId>spring-boot-starter-data-jpa</artifactId>
    </dependency>
    <dependency>
        <groupId>org.springframework.boot</groupId>
        <artifactId>spring-boot-starter-data-rest</artifactId>
    </dependency>
    <dependency>
        <groupId>org.springframework.boot</groupId>
        <artifactId>spring-boot-starter-thymeleaf</artifactId>
    </dependency>
    <dependency>
        <groupId>org.springframework.boot</groupId>
        <artifactId>spring-boot-starter-web</artifactId>
    </dependency>
    <dependency>
        <groupId>org.springframework.cloud</groupId>
        <artifactId>spring-cloud-gcp-starter</artifactId>
    </dependency>
    <dependency>
        <groupId>org.springframework.cloud</groupId>
        <artifactId>spring-cloud-gcp-starter-sql-mysql</artifactId>
    </dependency>
    <dependency>
        <groupId>mysql</groupId>
        <artifactId>mysql-connector-java</artifactId>
        <scope>runtime</scope>
    </dependency>
    <dependency>
        <groupId>org.projectlombok</groupId>
        <artifactId>lombok</artifactId>
        <optional>true</optional>
    </dependency>
</dependencies>


...

<dependencyManagement>
    <dependencies>
        <dependency>
            <groupId>org.springframework.cloud</groupId>
            <artifactId>spring-cloud-dependencies</artifactId>
            <version>${spring-cloud.version}</version>
            <type>pom</type>
            <scope>import</scope>
        </dependency>
        <dependency>
            <groupId>org.springframework.cloud</groupId>
            <artifactId>spring-cloud-gcp-dependencies</artifactId>
            <version>${spring-cloud-gcp.version}</version>
            <type>pom</type>
            <scope>import</scope>
        </dependency>
    </dependencies>
</dependencyManagement>
3. Let's start by creating a basic Employee entity as shown below
Employee.java
package pas.apj.pa.sb.gcp;

import lombok.AllArgsConstructor;
import lombok.Data;
import lombok.NoArgsConstructor;

import javax.persistence.*;

@Entity
@NoArgsConstructor
@AllArgsConstructor
@Data
@Table (name = "employee")
public class Employee {

    @Id
    @GeneratedValue (strategy = GenerationType.AUTO)
    private Long id;

    private String name;

}
4. Let's now add a Rest JpaRepository for our Entity
EmployeeRepository.java
package pas.apj.pa.sb.gcp;

import org.springframework.data.jpa.repository.JpaRepository;

public interface EmployeeRepository extends JpaRepository <Employee, Long> {
}
5. Let's create a basic RestController to show all our Employee entitiesEmployeeRest.java
package pas.apj.pa.sb.gcp;

import org.springframework.web.bind.annotation.RequestMapping;
import org.springframework.web.bind.annotation.RestController;

import java.util.List;

@RestController
public class EmployeeRest {

    private EmployeeRepository employeeRepository;

    public EmployeeRest(EmployeeRepository employeeRepository) {
        this.employeeRepository = employeeRepository;
    }

    @RequestMapping("/emps-rest")
    public List<Employee> getAllemps()
    {
        return employeeRepository.findAll();
    }
}
6. Let's create an ApplicationRunner to show our list of Employees as the applications starts up
EmployeeRunner.java
package pas.apj.pa.sb.gcp;

import org.springframework.boot.ApplicationArguments;
import org.springframework.boot.ApplicationRunner;
import org.springframework.stereotype.Component;

@Component
public class EmployeeRunner implements  ApplicationRunner {

    private EmployeeRepository employeeRepository;

    public EmployeeRunner(EmployeeRepository employeeRepository) {
        this.employeeRepository = employeeRepository;
    }

    @Override
    public void run(ApplicationArguments args) throws Exception {
        employeeRepository.findAll().forEach(System.out::println);
    }
}
7. Add a data.sql file to create some records in the database at application startupdata.sql
insert into employee (name) values ('pas');
insert into employee (name) values ('lucia');
insert into employee (name) values ('lucas');
insert into employee (name) values ('siena');
8. Finally our "application.yml" file will need to be able to be able to connect to our MySQL instance running in GCP as well as set some properties for JPA as shown below
spring:
jpa:
hibernate:
ddl-auto: create-drop
use-new-id-generator-mappings: false
properties:
hibernate:
dialect: org.hibernate.dialect.MariaDB53Dialect
cloud:
gcp:
sql:
instance-connection-name: fe-papicella:australia-southeast1:apples-mysql-1
database-name: employees
datasource:
initialization-mode: always
hikari:
maximum-pool-size: 1
A couple of things in here which are important.
- Set the Hibernate property "dialect: org.hibernate.dialect.MariaDB53Dialect" otherwise without this when hibernate creates tables for your entities you will run into this error as Cloud SQL database tables are created using the InnoDB storage engine.
ERROR 3161 (HY000): Storage engine MyISAM is disabled (Table creation is disallowed).
- For a demo I don't need multiple DB connections so I set the datasource "maximum-pool-size" to 1
- Notice how I set the "instance-connection-name" and "database-name" which is vital for Spring Cloud SQL to establish database connections
8. Now we need to make sure we have a database called "employees" as per our "application.yml" setting.

9. Now let's run our Spring Boot Application and verify this working showing some output from the logs
- Connection being established
2018-10-08 10:54:37.333 INFO 89922 --- [ main] c.google.cloud.sql.mysql.SocketFactory : Connecting to Cloud SQL instance [fe-papicella:australia-southeast1:apples-mysql-1] via ssl socket.
2018-10-08 10:54:37.335 INFO 89922 --- [ main] c.g.cloud.sql.core.SslSocketFactory : First Cloud SQL connection, generating RSA key pair.
2018-10-08 10:54:38.685 INFO 89922 --- [ main] c.g.cloud.sql.core.SslSocketFactory : Obtaining ephemeral certificate for Cloud SQL instance [fe-papicella:australia-southeast1:apples-mysql-1].
2018-10-08 10:54:40.132 INFO 89922 --- [ main] c.g.cloud.sql.core.SslSocketFactory : Connecting to Cloud SQL instance [fe-papicella:australia-southeast1:apples-mysql-1] on IP [35.197.180.223].
2018-10-08 10:54:40.748 INFO 89922 --- [ main] com.zaxxer.hikari.HikariDataSource : HikariPool-1 - Start completed.
- Showing the 4 Employee records
Employee(id=1, name=pas)
Employee(id=2, name=lucia)
Employee(id=3, name=lucas)
Employee(id=4, name=siena)
10. Finally let's make RESTful call as we defined above using HTTPie as follows
pasapicella@pas-macbook:~$ http :8080/emps-rest
HTTP/1.1 200
Content-Type: application/json;charset=UTF-8
Date: Mon, 08 Oct 2018 00:01:42 GMT
Transfer-Encoding: chunked
[
{
"id": 1,
"name": "pas"
},
{
"id": 2,
"name": "lucia"
},
{
"id": 3,
"name": "lucas"
},
{
"id": 4,
"name": "siena"
}
]
More Information
Spring Cloud GCP
https://cloud.spring.io/spring-cloud-gcp/
Spring Cloud GCP SQL demo (This one is using Spring JDBC)
https://github.com/spring-cloud/spring-cloud-gcp/tree/master/spring-cloud-gcp-samples/spring-cloud-gcp-sql-sample
Monday, 17 September 2018
PKS - What happens when we create a new namespace with NSX-T
I previously blogged about the integration between PKS and NSX-T on this post
http://theblasfrompas.blogspot.com/2018/09/pivotal-container-service-pks-with-nsx.html
On this post lets show the impact of what occurs within NSX-T when we create a new Namespace in our K8s cluster.
1. List the K8s clusters with have available
pasapicella@pas-macbook:~/pivotal/PCF/APJ/PEZ-HaaS/haas-148$ pks clusters
Name Plan Name UUID Status Action
apples small d9f258e3-247c-4b4c-9055-629871be896c succeeded UPDATE
2. Fetch the cluster config for our cluster into our local Kubectl config
pasapicella@pas-macbook:~/pivotal/PCF/APJ/PEZ-HaaS/haas-148$ pks get-credentials apples
Fetching credentials for cluster apples.
Context set for cluster apples.
You can now switch between clusters by using:
$kubectl config use-context
3. Create a new Namespace for the K8s cluster as shown below
pasapicella@pas-macbook:~/pivotal/PCF/APJ/PEZ-HaaS/haas-148$ kubectl create namespace production
namespace "production" created
4. View the Namespaces in the K8s cluster
pasapicella@pas-macbook:~/pivotal/PCF/APJ/PEZ-HaaS/haas-148$ kubectl get ns
NAME STATUS AGE
default Active 12d
kube-public Active 12d
kube-system Active 12d
production Active 9s
Using NSX-T manager the first thing you will see is a new Tier 1 router created for the K8s namespace "production"

Lets view it's configuration via the "Overview" screen

Finally lets see the default "Logical Routes" as shown below

When we push workloads to the "Production" namespace it's this configuration which was dynamically created which we will get out of the box allowing us to expose a "LoadBalancer" service as required across the Pods deployed within the Namspace
http://theblasfrompas.blogspot.com/2018/09/pivotal-container-service-pks-with-nsx.html
On this post lets show the impact of what occurs within NSX-T when we create a new Namespace in our K8s cluster.
1. List the K8s clusters with have available
pasapicella@pas-macbook:~/pivotal/PCF/APJ/PEZ-HaaS/haas-148$ pks clusters
Name Plan Name UUID Status Action
apples small d9f258e3-247c-4b4c-9055-629871be896c succeeded UPDATE
pasapicella@pas-macbook:~/pivotal/PCF/APJ/PEZ-HaaS/haas-148$ pks get-credentials apples
Fetching credentials for cluster apples.
Context set for cluster apples.
You can now switch between clusters by using:
$kubectl config use-context
3. Create a new Namespace for the K8s cluster as shown below
pasapicella@pas-macbook:~/pivotal/PCF/APJ/PEZ-HaaS/haas-148$ kubectl create namespace production
namespace "production" created
4. View the Namespaces in the K8s cluster
pasapicella@pas-macbook:~/pivotal/PCF/APJ/PEZ-HaaS/haas-148$ kubectl get ns
NAME STATUS AGE
default Active 12d
kube-public Active 12d
kube-system Active 12d
production Active 9s
Using NSX-T manager the first thing you will see is a new Tier 1 router created for the K8s namespace "production"

Lets view it's configuration via the "Overview" screen

Finally lets see the default "Logical Routes" as shown below

When we push workloads to the "Production" namespace it's this configuration which was dynamically created which we will get out of the box allowing us to expose a "LoadBalancer" service as required across the Pods deployed within the Namspace
Wednesday, 5 September 2018
Pivotal Container Service (PKS) with NSX-T on vSphere
It taken some time but now I officially was able to test PKS with NSX-T rather then using Flannel.
While there is a bit of initial setup to install NSX-T and PKS and then ensure PKS networking is NSX-T, the ease of rolling out multiple Kubernetes clusters with unique networking is greatly simplified by NSX-T. Here I am going to show what happens after pushing a workload to my PKS K8s cluster
First Before we can do anything we need the following...
Pre Steps
1. Ensure you have NSX-T setup and a dashboard UI as follows

2. Ensure you have PKS installed in this example I have it installed on vSphere which at the time of this blog is the only supported / applicable version we can use for NSX-T

PKS tile would need to ensure it's setup to use NSX-T which is done on this page of the tile configuration

3. You can see from the NSX-T manager UI we have a Load Balancers setup as shown below. Navigate to "Load Balancing -> Load Balancers"

And this Load Balancer is backed by few "Virtual Servers", one for http (port 80) and the other for https (port 443), which can be seen when you select the Virtual Servers link

From here we have logical switches created for each of the Kubernetes namespaces. We see two for our load balancer, and the other 3 are for the 3 K8s namespaces which are (default, kube-public, kube-system)

Here is how we verify the namespaces we have in our K8s cluster
pasapicella@pas-macbook:~/pivotal $ kubectl get ns
NAME STATUS AGE
default Active 5h
kube-public Active 5h
kube-system Active 5h
All of the logical switches are connected to the T0 Logical Switch by a set of T1 Logical Routers

For these to be accessible, they are linked to the T0 Logical Router via a set of router ports

Now lets push a basic K8s workload and see what NSX-T and PKS give us out of the box...
Steps
Lets create our K8s cluster using the PKS CLI. You will need a PKS CLI user which can be created following this doc
https://docs.pivotal.io/runtimes/pks/1-1/manage-users.html
1. Login using the PKS CLI as follows
$ pks login -k -a api.pks.haas-148.pez.pivotal.io -u pas -p ****
2. Create a cluster as shown below
$ pks create-cluster apples --external-hostname apples.haas-148.pez.pivotal.io --plan small
Name: apples
Plan Name: small
UUID: d9f258e3-247c-4b4c-9055-629871be896c
Last Action: CREATE
Last Action State: in progress
Last Action Description: Creating cluster
Kubernetes Master Host: apples.haas-148.pez.pivotal.io
Kubernetes Master Port: 8443
Worker Instances: 3
Kubernetes Master IP(s): In Progress
3. Wait for the cluster to have created as follows
$ pks cluster apples
Name: apples
Plan Name: small
UUID: d9f258e3-247c-4b4c-9055-629871be896c
Last Action: CREATE
Last Action State: succeeded
Last Action Description: Instance provisioning completed
Kubernetes Master Host: apples.haas-148.pez.pivotal.io
Kubernetes Master Port: 8443
Worker Instances: 3
Kubernetes Master IP(s): 10.1.1.10
The PKS CLI is basically telling BOSH to go ahead an based on the small plan create me a fully functional/working K8's cluster from VM's to all the processes that go along with it and when it's up keep it up and running for me in the event of failure.
His an example of the one of the WORKER VM's of the cluster shown in vSphere Web Client

4. Using the following YAML file as follows lets push that workload to our K8s cluster
apiVersion: v1
kind: Service
metadata:
labels:
app: fortune-service
deployment: pks-workshop
name: fortune-service
spec:
ports:
- port: 80
name: ui
- port: 9080
name: backend
- port: 6379
name: redis
type: LoadBalancer
selector:
app: fortune
---
apiVersion: v1
kind: Pod
metadata:
labels:
app: fortune
deployment: pks-workshop
name: fortune
spec:
containers:
- image: azwickey/fortune-ui:latest
name: fortune-ui
ports:
- containerPort: 80
protocol: TCP
- image: azwickey/fortune-backend-jee:latest
name: fortune-backend
ports:
- containerPort: 9080
protocol: TCP
- image: redis
name: redis
ports:
- containerPort: 6379
protocol: TCP
5. Push the workload as follows once the above YAML is saved to a file
$ kubectl create -f fortune-teller.yml
service "fortune-service" created
pod "fortune" created
6. Verify the PODS are running as follows
$ kubectl get all
NAME READY STATUS RESTARTS AGE
po/fortune 3/3 Running 0 35s
NAME TYPE CLUSTER-IP EXTERNAL-IP PORT(S) AGE
svc/fortune-service LoadBalancer 10.100.200.232 10.195.3.134 80:30591/TCP,9080:32487/TCP,6379:32360/TCP 36s
svc/kubernetes ClusterIP 10.100.200.1 443/TCP 5h
Great so now lets head back to our NSX-T manager UI and see what has been created. From the above output you can see a LB service is created and external IP address assigned
7. First thing you will notice is in "Virtual Servers" we have some new entries for each of our containers as shown below

and ...

Finally the LB we previously had in place shows our "Virtual Servers" added to it's config and routable

More Information
Pivotal Container Service
https://docs.pivotal.io/runtimes/pks/1-1/
VMware NSX-T
https://docs.vmware.com/en/VMware-NSX-T/index.html
While there is a bit of initial setup to install NSX-T and PKS and then ensure PKS networking is NSX-T, the ease of rolling out multiple Kubernetes clusters with unique networking is greatly simplified by NSX-T. Here I am going to show what happens after pushing a workload to my PKS K8s cluster
First Before we can do anything we need the following...
Pre Steps
1. Ensure you have NSX-T setup and a dashboard UI as follows

2. Ensure you have PKS installed in this example I have it installed on vSphere which at the time of this blog is the only supported / applicable version we can use for NSX-T

PKS tile would need to ensure it's setup to use NSX-T which is done on this page of the tile configuration

3. You can see from the NSX-T manager UI we have a Load Balancers setup as shown below. Navigate to "Load Balancing -> Load Balancers"

And this Load Balancer is backed by few "Virtual Servers", one for http (port 80) and the other for https (port 443), which can be seen when you select the Virtual Servers link

From here we have logical switches created for each of the Kubernetes namespaces. We see two for our load balancer, and the other 3 are for the 3 K8s namespaces which are (default, kube-public, kube-system)

Here is how we verify the namespaces we have in our K8s cluster
pasapicella@pas-macbook:~/pivotal $ kubectl get ns
NAME STATUS AGE
default Active 5h
kube-public Active 5h
kube-system Active 5h
All of the logical switches are connected to the T0 Logical Switch by a set of T1 Logical Routers

For these to be accessible, they are linked to the T0 Logical Router via a set of router ports

Now lets push a basic K8s workload and see what NSX-T and PKS give us out of the box...
Steps
Lets create our K8s cluster using the PKS CLI. You will need a PKS CLI user which can be created following this doc
https://docs.pivotal.io/runtimes/pks/1-1/manage-users.html
1. Login using the PKS CLI as follows
$ pks login -k -a api.pks.haas-148.pez.pivotal.io -u pas -p ****
2. Create a cluster as shown below
$ pks create-cluster apples --external-hostname apples.haas-148.pez.pivotal.io --plan small
Name: apples
Plan Name: small
UUID: d9f258e3-247c-4b4c-9055-629871be896c
Last Action: CREATE
Last Action State: in progress
Last Action Description: Creating cluster
Kubernetes Master Host: apples.haas-148.pez.pivotal.io
Kubernetes Master Port: 8443
Worker Instances: 3
Kubernetes Master IP(s): In Progress
3. Wait for the cluster to have created as follows
$ pks cluster apples
Name: apples
Plan Name: small
UUID: d9f258e3-247c-4b4c-9055-629871be896c
Last Action: CREATE
Last Action State: succeeded
Last Action Description: Instance provisioning completed
Kubernetes Master Host: apples.haas-148.pez.pivotal.io
Kubernetes Master Port: 8443
Worker Instances: 3
Kubernetes Master IP(s): 10.1.1.10
The PKS CLI is basically telling BOSH to go ahead an based on the small plan create me a fully functional/working K8's cluster from VM's to all the processes that go along with it and when it's up keep it up and running for me in the event of failure.
His an example of the one of the WORKER VM's of the cluster shown in vSphere Web Client

4. Using the following YAML file as follows lets push that workload to our K8s cluster
apiVersion: v1
kind: Service
metadata:
labels:
app: fortune-service
deployment: pks-workshop
name: fortune-service
spec:
ports:
- port: 80
name: ui
- port: 9080
name: backend
- port: 6379
name: redis
type: LoadBalancer
selector:
app: fortune
---
apiVersion: v1
kind: Pod
metadata:
labels:
app: fortune
deployment: pks-workshop
name: fortune
spec:
containers:
- image: azwickey/fortune-ui:latest
name: fortune-ui
ports:
- containerPort: 80
protocol: TCP
- image: azwickey/fortune-backend-jee:latest
name: fortune-backend
ports:
- containerPort: 9080
protocol: TCP
- image: redis
name: redis
ports:
- containerPort: 6379
protocol: TCP
5. Push the workload as follows once the above YAML is saved to a file
$ kubectl create -f fortune-teller.yml
service "fortune-service" created
pod "fortune" created
6. Verify the PODS are running as follows
$ kubectl get all
NAME READY STATUS RESTARTS AGE
po/fortune 3/3 Running 0 35s
NAME TYPE CLUSTER-IP EXTERNAL-IP PORT(S) AGE
svc/fortune-service LoadBalancer 10.100.200.232 10.195.3.134 80:30591/TCP,9080:32487/TCP,6379:32360/TCP 36s
svc/kubernetes ClusterIP 10.100.200.1
Great so now lets head back to our NSX-T manager UI and see what has been created. From the above output you can see a LB service is created and external IP address assigned
7. First thing you will notice is in "Virtual Servers" we have some new entries for each of our containers as shown below

and ...

Finally the LB we previously had in place shows our "Virtual Servers" added to it's config and routable

More Information
Pivotal Container Service
https://docs.pivotal.io/runtimes/pks/1-1/
VMware NSX-T
https://docs.vmware.com/en/VMware-NSX-T/index.html
Subscribe to:
Posts (Atom)